HPC introduction
On day 2, we work on Crunchomics, the Genomics Compute Environment for SILS and IBED. Crunchomics is an HPC (high-performance computer): a group of powerful computers that many people share. If you work at IBED, you can get access to it as described on the Before you start page.
Working on an HPC is a bit different from working on your own computer. The figure below gives a simplified overview:
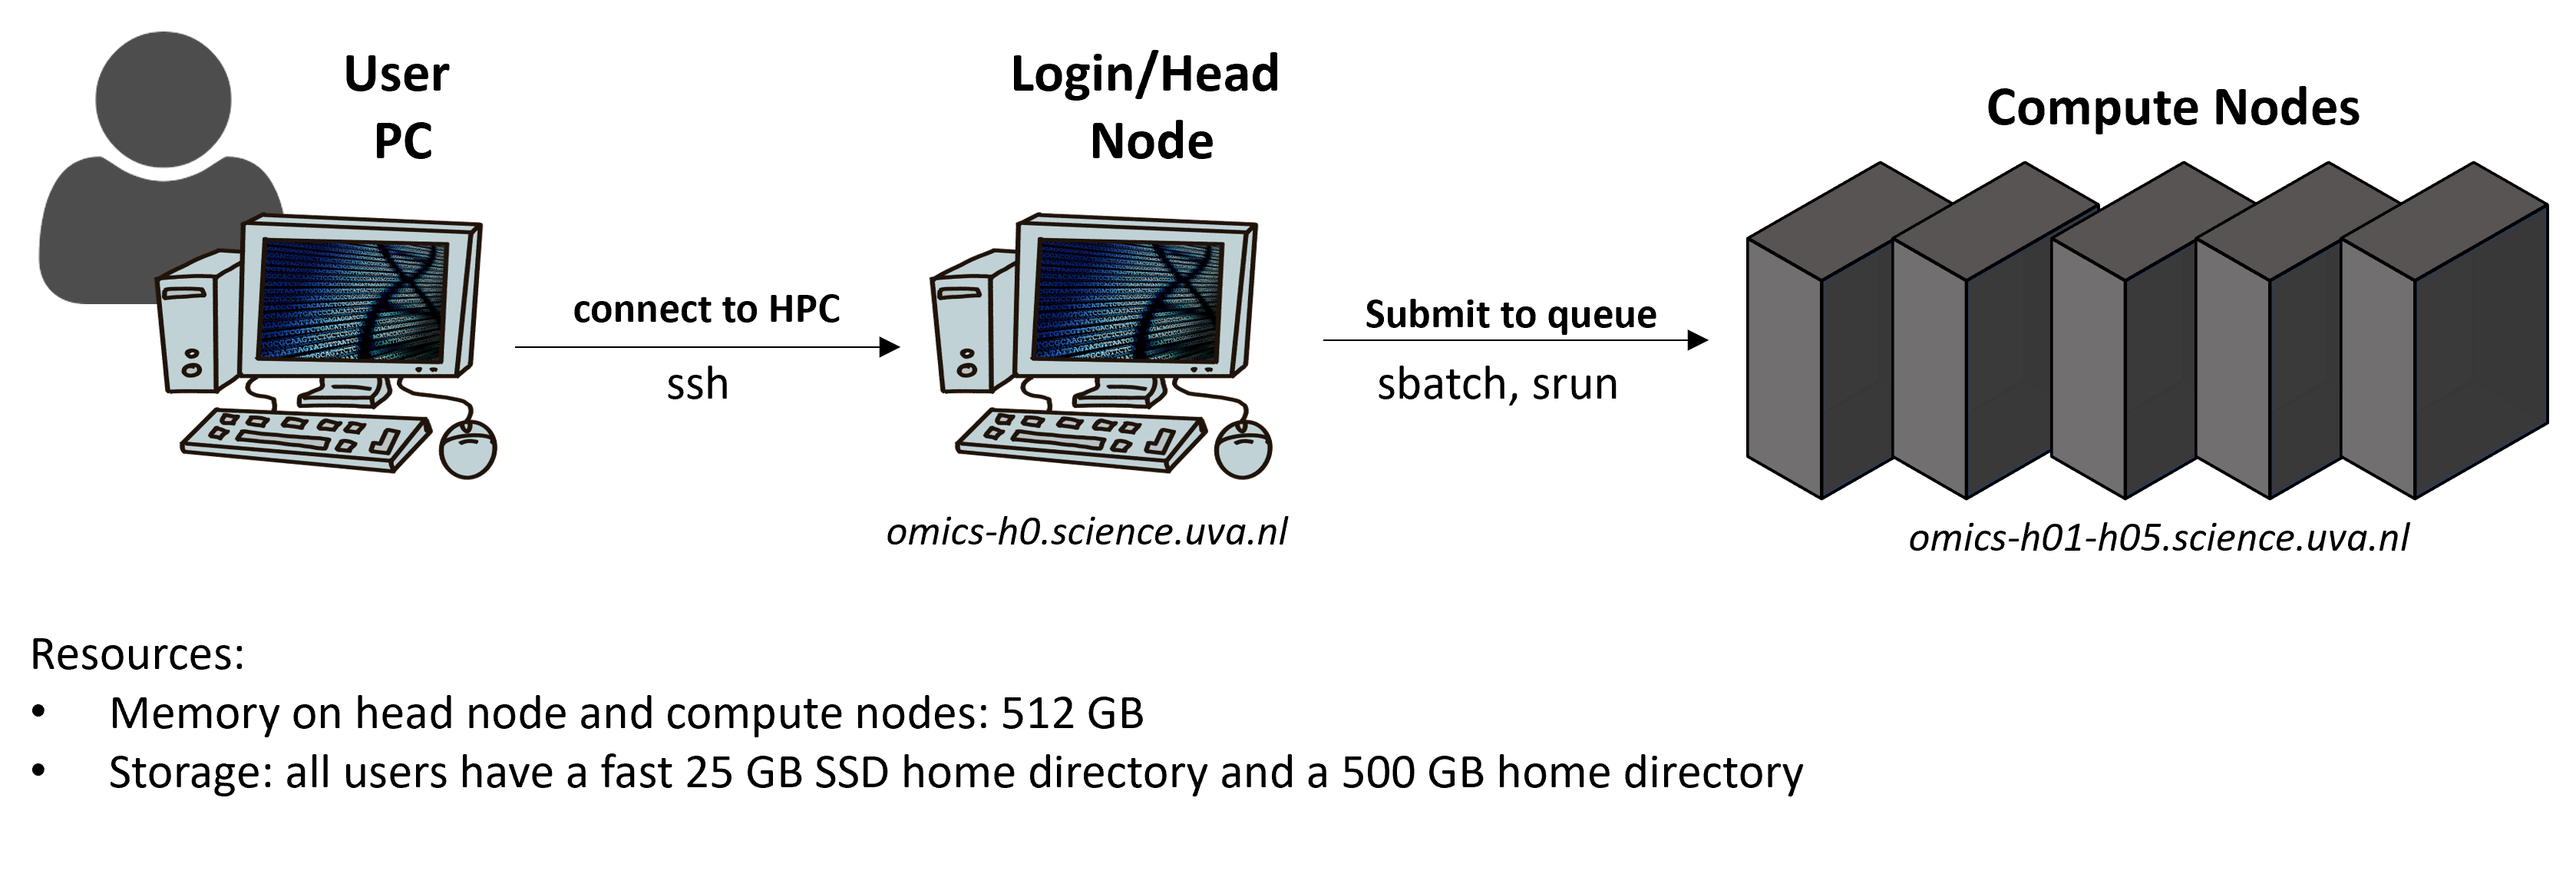
- You log in from your own computer with
ssh, as in the check on the Before you start page (the left arrow in the figure). - When you log in, you arrive on the login node, also called the head node. This computer is for preparing your work, for example moving and editing files and writing job scripts. It is not for running analyses.
- The analyses run on the compute nodes. These computers have many more CPUs and much more memory.
- A CPU is what does the calculations, so more CPUs means more work can get done at the same time.
- Memory (RAM) is the working space a program uses while it runs.
- Memory is not the same as storage, which is where your files are kept.
- In between is SLURM, a workload manager (also called a scheduler) that is used on many large HPCs. You send your analysis to SLURM as a job, and SLURM runs it on a compute node. In the figure, this is the arrow “Submit to queue”.
sbatchandsrunare the two commands that send a job to SLURM. We use both on the next page. SLURM does three things:- It gives users access to CPUs and memory on the compute nodes, for a limited time
- It starts and runs the jobs, and lets you check on them
- It manages the queue: the list of jobs that wait until enough CPUs and memory are free
You share Crunchomics with many other people, so only ask for the resources that you actually use. There are no hard limits, but please follow these rules:
- Do NOT run jobs that need many CPUs or a lot of memory on the login node (
omics-h0). Use the compute nodes (omics-cn001toomics-cn005) for this - Do NOT use more than 20% of the CPUs or memory of the cluster for more than a day. If you have large jobs, contact Wim de Leeuw
- Don’t leave resources that you reserved unused, and set reasonable time limits on your jobs
- Use the queue (SLURM) for large jobs. Working interactively is possible, but not for large jobs. We learn how to use the queue on day 2
- Close programs when you don’t use them anymore, for example an R session
You learn how to ask for resources and time on the next page, please look back into the etiquette rules once you run your own analyses.
Storage
On Crunchomics, you have two folders ($USER stands for your user name):
- Your home directory,
/home/$USER, with 25 GB of space - Your personal directory,
/zfs/omics/personal/$USER, with 500 GB of space. Since this directory is larger, you want to run all your analyses and install all software in this directory. On day 2, we make a shortcut to it,~/personal, and keep our project folder there
Good to know:
- Your data is removed from Crunchomics when your UvAnetID expires
- If you need more space, or a shared folder for a larger project with several team members, contact the Crunchomics team
- Snapshots: Crunchomics automatically makes snapshots, saved copies of your files, without you having to do anything. It makes one every hour, which is kept for 24 hours, and one every day around midnight, which is kept for a week. So if you delete a file by mistake, you can still get it back for up to a week. You can look at the snapshots and read the files in them in the hidden
.zfs/snapshotfolder, for example withls /zfs/omics/personal/$USER/.zfs/snapshot. But snapshots also mean that files you delete still count towards your storage limit until the last snapshot with them is removed. Keep this in mind if you make many or large temporary files. If you need a file restored, or snapshots removed to free up space, contact Wim de Leeuw - Your data is stored on several disks, which protects it if one disk breaks. But it is not copied anywhere else. Crunchomics is not a backup or an archive. You are responsible for backing up your own data. The website of the IBED computational support team explains the archiving options at the UvA
Compute resources
- Crunchomics has 5 compute nodes, each with 64 CPUs and 512 GB of memory
- If you need more resources, or GPUs, see the website of the IBED computational support team
- You find more information in the Crunchomics documentation
On the next page, we copy the sequencing data from day 1 to Crunchomics and get read statistics with seqkit. Then we clean the reads with fastp, which we install ourselves with conda, a tool to install software. On the way, we learn different ways to send jobs to the compute nodes with SLURM.